
AI-Enabled Network & Data Center Services
Infrastructure Built for Hyperscale.
Infrastructure to optimization. Handled end-to-end. Accelerate your network and data center operations with two decades of engineering pedigree and intelligent automation.
Design & Architecture
L1–L3 network, DC Connectivity & end-to-end DC design.
Deployment at Scale
Rack & stack, cabling, migration & cutover.
On-Site Smart Hands
Dedicated, named teams at every site.
Asset & RMA Lifecycle
Inventory, audits & end-to-end RMA logistics.
AI & Automation
AI OpsHub & Lynx built into every phase.
Program Management
Multi-site rollout waves & governed cadence.
Proven at hyperscale
Uptime
Across 600+ sites — zero unplanned outages
SLO compliance
With full NOC transition in under 90 days
Peering capacity
Record capacity delivered for a global platform
Inventory optimized
For a global hyperscaler ($260M → $150M)
Global delivery & practice depth
Countries with field coverage
DC design engineers
Certified technician pipeline
Global NOC & optical ops
Locations in one lab-ops engagement
The scale ceiling
Why Infrastructure Operations Fail at Scale
Design Backlogs Stall Growth
Don't let deployment capacity throttle your ambitions. Accelerate design-to-build, hit your launch dates, and adopt new tech on your timeline.
Vendor Sprawl, Inconsistent Quality
Revolving doors. Unfamiliar faces. Costly drift. Critical sites can't afford a rotating cast. Lock in dedicated teams, hold the line on quality, and keep every region in lockstep.
Manual Provisioning Can't Scale
Manual provisioning breeds delays and errors. Don't let slow circuit delivery undermine reliability when data demands surge.
Tribal Knowledge & Asset Chaos
Fragmented maps. Missing inventory. Untracked RMAs. When your key engineers leave, your network memory walks out the door. Stop waiting for the next audit to expose gaps.
Capabilities
How we support data centers and networks
Design → Deploy → Operate → Optimize. The entire infrastructure lifecycle under one roof with AI and automation engineered into every phase.
Design & architecture
+
Network architecture, structured cabling, data halls, rack lay out, and end-to-end data center design — accelerated by design automation tooling and delivered as complete design packages.
- Network architecture & design (L1–L3)
- Structured cabling, wireless design & site surveys
- OSP/ISP, QoS & DWDM design
- End-to-end DC design — BIM, layout, space & power
- Design packages: SOW, BOM, containment, UPS
2–6 week assessment engagements • Field coverage in 19+ countries
Implementation & deployment
+
Greenfield and brownfield delivery from rack-and-stack through commissioning, with testing, provisioning, and cutover handled end to end.
- Rack & stack, structured cabling install & testing
- Device configuration, imaging, burn-in & turn-up
- Circuit provisioning, cross-connects & activations
- Migration, cutover & OSP/ISP testing
- Commissioning, rip & replace, recommissioning
2–6 week assessment engagements • Field coverage in 19+ countries
Operations & support
+
24/7 follow-the-sun operations with ITIL 3-tier incident response, root cause analysis, and dedicated on-site coverage.
- 24/7 network monitoring & NOC services
- ITIL 3-tier incident response & break-fix with RCA
- Change management & preventative maintenance
- MACDs, DWDM operations & peering services
- On-site Smart Hands & wall-to-wall white space ops
2–6 week assessment engagements • Field coverage in 19+ countries
Infrastructure management
+
Full asset lifecycle transparency, from receiving and inventory through RMA handling and capacity optimization.
- Asset management & logistics (receiving, storage, cage delivery)
- Inventory & audit with serial capture
- Vendor management & end-to-end RMA handling
- Capacity planning & optimization
- KPI & BI dashboards
2–6 week assessment engagements • Field coverage in 19+ countries
Program & project management
+
Coordinated delivery across backbone and DC projects, with governance that runs from weekly ops reviews to yearly business reviews.
- Backbone + DC project coordination & management
- Project intake & BOM creation
- Rollout program management for multi-site waves
- Service delivery governance — yearly, monthly, weekly cadence
2–6 week assessment engagements • Field coverage in 19+ countries
AI, automation & data
+
AI engineering and data capability that turns runbooks into agents, dashboards into decisions, and manual toil into automated workflows.
- AI engineering, data & innovation
- Data analytics, KPIs, BI & dashboard creation
- GIS and OSS/BSS development
- AI OpsHub & Lynx platform enablement
- Solution accelerators (SD-WAN, network automation, DC setup)
2–6 week assessment engagements • Field coverage in 19+ countries
Why clients choose us (and stay)
Built to own the lifecycle, not hand it off
One accountable team from design through decommissioning.
End-to-End Lifecycle Ownership
Design → Install → Operations → Decommissioning, enhanced by AI and automation. One team eliminates handoff risk and compresses timelines.
Service Catalog–Driven Delivery
Field-tested playbooks and reusable frameworks accelerate onboarding and standardize execution across every site.
Direct Client Revenue Impact
Our operations are proven to directly support more than $10M in annualized client revenue.
Scalable Staffing & Modular Models
Flexible support models for colo, data center, and edge — burst labor, traveling techs, and dedicated teams that flex with demand.
Practice-Led Expertise
Industry veterans with hyperscaler, telco, and enterprise experience lead every engagement.
AI-Enabled Throughout
AI OpsHub and Lynx applied across operations — automation, monitoring intelligence, and data-driven decisions built into every phase.
Proprietary platform & AI engine
Proprietary intelligence that accelerates infrastructure
Built directly into Astreya's managed service model, automating resolution, encoding runbooks, and illuminating operations across network and data center operations.
Unified operations cockpit
AI OpsHub
Where our engineers and AI agents work side by side.
Explore AI OpsHubBuilt directly into how Astreya delivers managed services · Complements your existing tooling without replacement
Global delivery footprint
Proven where scale, uptime, and consistency are non-negotiable.
Our clients include global hyperscalers, Fortune 10 technology companies, global financial services firms, and the largest social media, streaming, and e-commerce platforms.
01
Colo Coordination
- Equinix
- Digital Realty
- NTT
- EdgeConnex · Switch / Aligned
02
Coverage Regions
- AMER
- EMEA
- APAC
- 19+ countries, 24/7
03
Technician Pipeline
- L1–L4 certified
- CompTIA
- BICSI
- Cisco, Juniper certifications
04
Environments
- Hyperscale data centers
- Colocation facilities
- Research labs
- Edge sites
Proof at scale
Results from the world's largest technology environments
How hyperscalers and global platforms partner with Astreya to build, run, and optimize infrastructure.
Smart Hands consistency across 120+ global colos
Two of the world's largest digital platforms needed Smart Hands support across massive colocation footprints without the uneven quality and delays that come with rotating technicians. Astreya deployed dedicated, named teams across every site, with rack-and-stack, precision cabling, connectivity testing, PDU power balancing, strict MOP adherence, and comprehensive DCIM documentation.
0 unplanned outages in transition & steady state · 30+ sites covered by 4 techs + PM + asset specialist
99.9%
Uptime across all supported locations
120+
Colo sites served by one dedicated team
Global streaming & gaming leader · Global e-commerce enterprise
A NOC takeover that earned 3× the scope
The client's network operations center (NOC) couldn't keep up with growth. There was no consistent way to measure service levels and break-fix capacity fell short. Monitoring, POP maintenance, circuit repair, and asset upkeep all needed to scale at once. Astreya completed the full service transition ahead of schedule. From day one, the team established live monitoring for ticket queues and workforce utilization. We also used automation, AI, and ML to reduce outage times.
3× scope expansion earned post-performance · AI/ML automation instituted to reduce outages
98%
SLO compliance against client targets
<90 days
Kickoff to full service transition
One of the world's largest social network companies
Circuit provisioning at record-setting capacity
Manual circuit provisioning was causing delays and errors, and network reliability was slipping. Operations couldn't scale fast enough to keep up with rapidly growing data demand. Astreya streamlined circuit provisioning from end to end and automated peering, supported by business intelligence tooling. The team also automated monthly operation reviews, and deepened vendor collaboration to improve scalability and reliability.
57 circuits (10G/100G) delivered monthly on average · 90+ circuits in peak high-demand months
44.90T
Record peering capacity achieved
3.7T
Average peering capacity per month
World's most popular social networking platform
Clearing a data center design backlog at cloud speed
Rapid growth created a design backlog. With a planned regional expansion of more than 60%, every project required manual, custom design work. Data center builds were delayed, new product offerings were postponed, and staff were burning out. Astreya embedded specialized design engineers alongside the client's team and set AutoCAD drawing standards to keep work consistent. A remote team model let Astreya ramp up quickly, and the team helped automate the client's design tools.
Backlog reduced with improved delivery reliability · Automation: layout validation, auto-generated BOM/SOW, patch matrices
+150%
Design artifact velocity per sprint
60+
Design engineers available for DC design
Global cloud infrastructure provider
From tribal knowledge to autonomous AI agents
Poor data quality meant engineers didn't trust their dashboards. On-call, triage, and reporting ran on manual effort and tribal knowledge, and the codebase wasn't ready for AI tools. Astreya unified topology data into a reliable operational data store. The team turned runbooks into autonomous agents and built 10+ AI skills and agents using Claude, including code review, on-call monitoring, triage, and daily briefings. Astreya also made the codebase AI-ready with semantic models and structured documentation.
1 real-time view of end-to-end network data · 0 tribal-knowledge risk — processes live in AI runbooks
85%
Reduction in operational toil
10+
AI skills & agents operating autonomously
Global social networking platform
Insights & thought leadership
Go deeper into network, data center, and AI operations
Explore case studies, AI frameworks, and strategic perspectives from Astreya's infrastructure and automation leaders.
How Astreya Managed a 115% Surge in Network Tickets With AI
See how Astreya used AI agents to manage a 115% increase in network tickets and improve root cause accuracy to 95%, all while limiting headcount growth to 6%.
Read article →
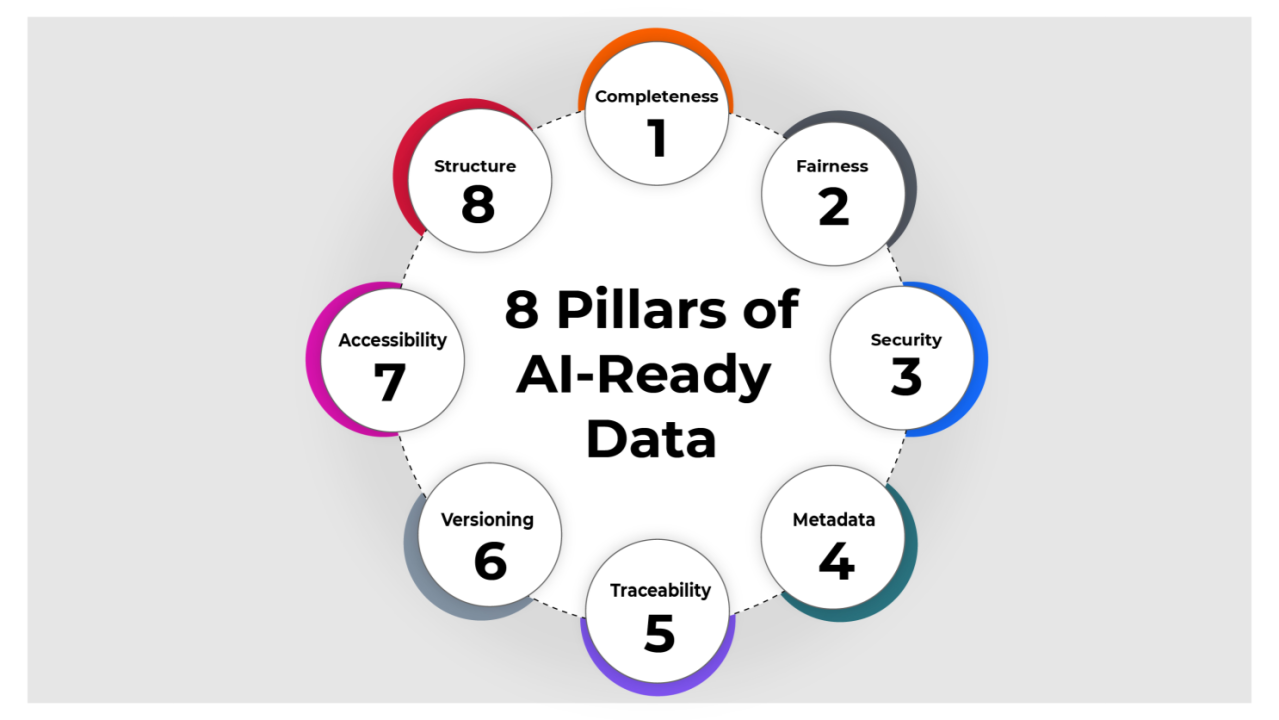
Why AI Investments Fail Before Production—and How AI-First MSPs Close the Data Gap
Most AI projects fail before production because the underlying data is not AI-ready. Learn how active governance and AI-first MSPs improve AI ROI.
Read article →
Agentic AI Is a Cloud Platform Problem, Not a Model Problem
Learn how a shared platform can stop AI agent sprawl and keep identity, governance, and costs under control across multi-cloud environments.
Read article →Network & Data Center FAQ
Frequently asked questions
Everything you need to know about our infrastructure lifecycle services, delivery models, and global coverage.
Have a specific question?
Our infrastructure architects are available to review your current environment, project pipeline, and operational requirements.
What are network and data center lifecycle services?
+
Lifecycle services cover the full arc of infrastructure ownership: design (architecture, cabling, DC layout), deployment (rack and stack, provisioning, migration), operations (24/7 NOC, incident response, Smart Hands), and optimization (asset management, capacity planning, AI automation). One accountable team owns every phase instead of scattering it across vendors.
What is the difference between Smart Hands and remote NOC support?
+
Smart Hands is on-site, physical work at data centers and colos — racking equipment, running cabling, swapping hardware, performing audits. An NOC provides remote 24/7 monitoring, incident response, and change management. Astreya delivers both under one engagement, so remote detection and on-site resolution are coordinated by the same team.
How does an engagement typically start?
+
Most engagements start with a 2–6 week assessment, audit, or design engagement that produces a roadmap. Findings then convert to project execution — deployments, migrations, standups, automation sprints — and mature into steady-state, multi-year managed operations with governed SLAs.
What geographies do you cover?
+
Field services coverage spans 19+ countries across AMER, EMEA, and APAC, with 24/7 follow-the-sun NOC and optical network operations. We've supported 150+ locations in a single lab-ops engagement and delivered full data center standups for clients entering new regions.
Can you handle fluctuating project volume?
+
Yes — that's what our modular staffing model is built for. Just-in-time burst labor, traveling tech teams, and Smart Hands dispatch scale up and down with deployment waves, so you're not paying for idle headcount between projects or missing windows during surges.
How does AI improve infrastructure operations?
+
AI OpsHub and Lynx are applied across every phase — automation, monitoring intelligence, and data-driven decisions. In practice: runbooks encoded into autonomous AI agents, event-driven automation replacing manual polling and checks (an 85% reduction in operational toil in one engagement), and hardware tickets auto-processed before a technician is engaged.
Do you manage decommissioning and migrations?
+
Yes — coordinated decommissioning includes site visits, full inventory capture (models, serials, MACs), stakeholder scheduling, off-hours execution, and hardware manifests for reuse or recycling, with certified e-waste handling. Engagements at scale have decommissioned thousands of rooms with zero disruption to daily operations.
How do you maintain quality across dozens of sites?
+
The same dedicated, named teams work across every site, building knowledge that rotating technicians can't replicate. These teams are backed by service-catalog playbooks, strict MOP adherence, and DCIM documentation. That model has sustained 99.9% uptime across 30+ colos with zero unplanned outages.